Keep the thread from search to site.
Querywright is the SEO operating layer for Claude and ChatGPT. It gives the AI you already use the evidence and the memory to run SEO on a site over time: research, measured search demand, Google’s own results, a plan a person approves, copy a person accepts, checks before anything ships, and what happened after. The AI does the thinking. Querywright keeps the record, signs it, and never calls a model itself.
/ four evidence states · never collapsed into one
Project breakdown
Replace one Semrush subscription. Find out if there’s a product underneath.
Querywright started on August 3, 2026 as the Keyword Opportunity Engine, an internal tool for ACMeridian. The first goal was modest and already paid for itself on paper: a direct DataForSEO integration with caching, a keyword table, filtering, CSV export, and cost logging, so the company could stop renting keyword research by the seat.
The second goal was the interesting one, and the brief refused to conflate the two. Keyword tools are good at answering what exists and what it costs. The valuable question is what you should actually build. That page-level decision engine had to earn its engineering time with evidence from real studio work before it became a product requirement. It did, and then it changed shape twice.
Three weeks in, I deleted the clever half.
Version two grew fast into a control plane: a contract kernel describing what a site should be, a deterministic verifier checking whether it obeyed, an evidence registry, a findings layer, and CI enforcement. On top of that sat the question that mattered: could a language model interpret all that deterministic state without inventing any of it?
Instead of assuming, I ran an evaluation phase with zero product integration. A frozen adversarial corpus, at least three runs per case, a provider-agnostic interface so no vendor leaked into the domain, and hard grounding gates that failed a run for any unknown source ID, unsupported number, or provenance slip. A local Gemma model on an RTX 5090 was the reference benchmark. The results drew a clean line through the product.
On August 26 the reset shipped as an architecture decision. Hosted AI analysis, strategy adjudication, contract materialization, and the governance ceremony around them were retired. What stayed was the chassis: provider truth, measured demand, crawl inventory, evidence provenance, and a read-only MCP surface. The new division of labor is one sentence. The host AI owns semantic mappings, rationale, prose, and review. Querywright owns evidence identity, measurements, immutable artifacts, and deterministic verification. Querywright itself never calls a model, and it still doesn’t.
Your AI does the thinking. You decide what ships.
The public product is a loop of six jobs: understand the site, decide what each page should target, create the copy, check it before it ships, observe what happens after, and reconsider. The AI does the understanding and the drafting. The deciding belongs to a person. Underneath, the engine keeps the stricter shape it has had since the reset: recorded steps from research to verification, with exactly two human authority events, approving a strategy and accepting exact copy. There is no third approval and no confirmation artifact, so a recommendation can never quietly become a decision.
- Next.js 16 on Cloudflare Workers through OpenNext at
app.querywright.com, Postgres through Hyperdrive, Drizzle ORM, 106 tables across 76 migrations - Multi-tenant since September, with row-level security on customer data in the database itself. Public sign-up opened on September 20
- Research, approved strategies, generation briefs, reviewed copy and verification results carry an HMAC-SHA256 tag made on the server, so an artifact is authenticated, not just stored
- Generation briefs hand the AI a bounded context: 4,000 characters for an existing page, 16,000 for a new page’s site context, and up to five 4,000-character evidence ranges
- After publishing, the loop keeps going: Search Console, weekly rank checks on desktop and mobile, Google Analytics outcomes and Local SEO, each kept as dated observations from its own source. A rank check the provider fails is retried once, four hours later, rather than waiting a week
One workspace per site, showing what the AI reads.
Until October the App was organised by artifact type: a site map, then strategies, briefs, reviewed copy and verifications, each on its own screen. It showed less than half of the evidence the product keeps, opened a page in a 345-pixel drawer, and carried the site in a query parameter on every route. The overhaul, released on October 11, rebuilt it as one workspace per site with six sections: Overview, Pages, Work, Performance, Evidence and History.
The new sections are read-only evidence surfaces. Each one returns the same derivation the MCP tools give an AI host, unchanged, so the App and the AI cannot disagree about what is true, and none of them adds a score, a health percentage or a recommendation of its own.
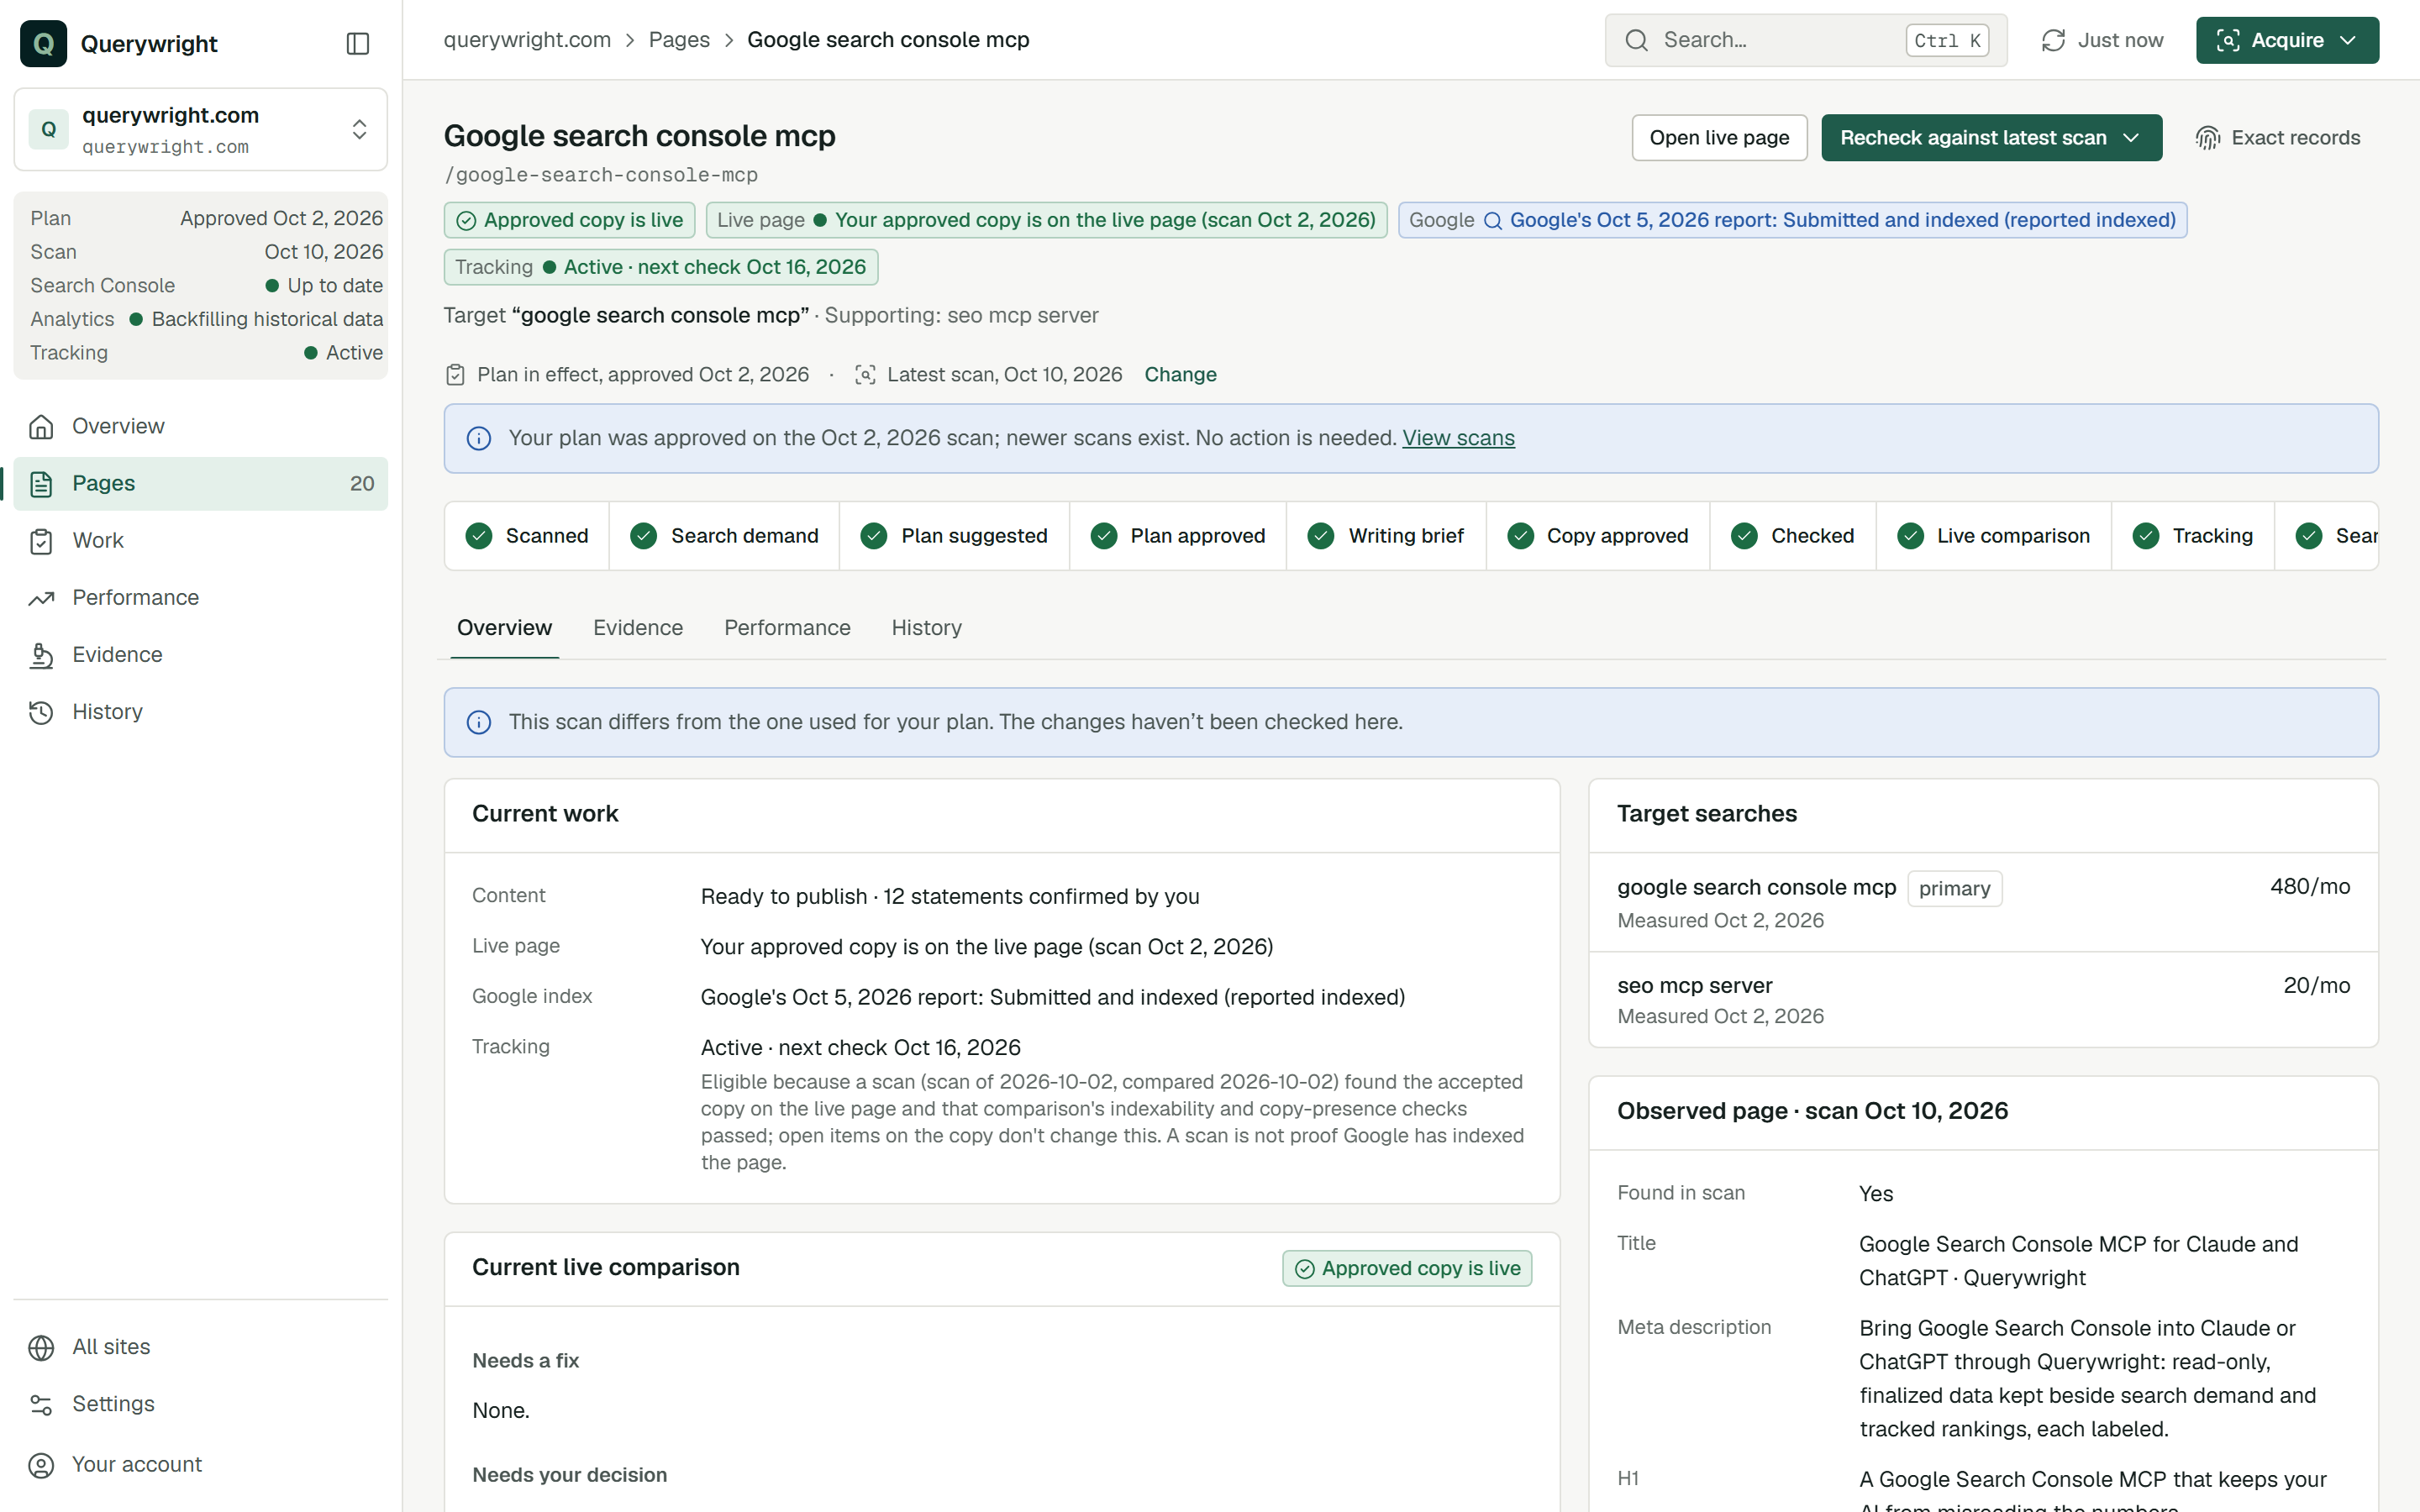
/google-search-console-mcp on querywright.com, the site Querywright runs its own SEO through. The status lines keep Querywright’s scan, Google’s report and the tracking schedule apart, and the strip under them is the page’s journey. Captured October 2026.- URLs from the old App answer with a 308 to their new home, so links into the September screens still land
- The overhaul’s first production dogfood was rejected: 68 of 164 page loads failed with a 503. After three fixes, 184 loads came back clean and 90 sequential reads had no failures, and only then was it released
- Accessibility and visual-regression acceptance now run against the App, alongside the browser suite
The AI gets a key to the library, not the vault.
mcp.querywright.com is a separate Cloudflare Worker exposing 46 tools to
Claude, ChatGPT or any MCP-capable host. It reads Postgres through a dedicated role that
can only SELECT, and only from the tables its read tools need. Everything
that writes or spends, from an approval to a demand measurement, goes through narrow
service bindings to the App, so provider credentials never enter the MCP bundle. Every
JSON request is capped at one mebibyte, because a host that can send a reviewed-copy
payload can also send a bomb.
- Seven tools draw on a site’s included allowance, four of them by contacting DataForSEO, and each says so in its own description, so a host can tell its user before a cache miss costs anything
- The Search Console tools use no allowance at all
- An inconclusive rank check is a read state, not a drop: the last reliable position is kept and the stored rows are never rewritten
A front door that shows the App.
querywright.com was rebuilt in October around one line, Let AI run your
SEO, and one proof: the App itself. The hero plays a 17.75-second tour recorded
from a real session on querywright.com, moving through the overview, a page, the work
plan, rankings, Search Console and evidence. Every frame passed a redaction audit for
account identifiers before it shipped, and the stills on the site went through the same
audit.
It is Astro 7 with the docs in MDX, one typeface, Geist, and a quiet palette: a
near-white canvas, a single forest accent, and the brand greens from #051f20
to #daf1de kept for a few moments.
- Content Security Policy with no
unsafe-inlineand nounsafe-eval, and style attributes refused outright. The build hashes what Astro emits and writes the headers file itself - Checked with axe against WCAG 2.2 AA at 390 and 1440 pixels, across 116 page views
- One price in public: a Founding Beta at $99 a month for the first ten paying customers, locked for twelve months
Six sites, and the fixes they asked for.
As of October 19, Querywright’s Search Console connection covers six sites: its own, Fonthead, and ACMeridian’s company site and its three new referral sites. ACMeridian’s two pages for contractors target searches Querywright measured, under a plan approved in it on October 17: “tree service leads” and “appliance repair leads”, about 210 searches a month each across the US. The same record set aside “thumbtack alternative”, because the results for it are consumer apps.
Real sites found the next round of work:
- New sites with no impressions yet: the Search Console import stopped at Google’s empty days, and the three referral sites had stored none of their 93. It now keeps going past them
- Local results that aren’t local: when fewer than one in ten organic rows name the place searched, the observation is flagged and a re-check is recommended. Of the first eighteen observations, it flagged nine
- A redirect is the requested URL’s own answer, never the destination’s content, before publishing as well as after, so a brief refuses a target that redirects
- A complete mobile check without the site now says “not in the top 50” instead of a provider’s count of zero results
- When a renewal webhook was late on October 15, Querywright refused work for its own account. It now re-reads Stripe before a paid check and in a sweep every four hours, so a paying customer is not locked out by a late or missing message
Two things every customer needs arrived in October as well. The owner of an account can export its data as one archive: JSON Lines for every kind of record, CSV copies of the large tables, a Markdown file for each piece of accepted copy, and a manifest that records a checksum for every file, with supplier costs and payment identifiers left out. And Support stores a request under its own reference before it emails anyone, and reads an account’s diagnostics only with the customer’s consent, read-only.
What I picked, and what I didn’t.
-
01
nullis not zero.A provider returning no data for a phrase and a provider measuring a real zero are different facts, and the second is more valuable than the first. Querywright keeps four states distinct all the way down: measured positive, measured zero, no provider evidence, unmeasured. Nullable columns, explicit checks in every aggregation, and tests that assert the two never merge. Different sources may disagree without overwriting each other, and no source is canonical by default. It is the second ADR in the repo, and the rule has since reached plan usage too: a null count means unknown or unmetered, never zero.
Considered: coercing missing to 0 like every dashboard does, dropping unmeasured rows, last-write-wins merging across providers
-
02
The product never calls a model.
I built hosted AI analysis, evaluated it properly against a frozen corpus with grounding gates, and then retired it. The evaluation showed that the machine’s judgment is most useful when it sits on the host side, where the user already has a model they trust, and Querywright’s job is to make that judgment checkable. Host judgments are not evidence. Approval is a decision, never an inference. The product got smaller and became honest about what it knows, and the public pitch, Let AI run your SEO, is that same split said plainly.
Considered: a qualified hosted model behind the UI (built, measured, retired), an opportunity score, keyword difficulty, a traffic forecast
-
03
The App reads what the AI reads.
When the App was rebuilt, the easy path was a dashboard: a health score, a traffic-light summary, a suggested next step. Instead every section returns the product’s own site-work read unchanged, the same one an AI host gets through MCP, with no provider call, no score or composite, and no new authority. Earlier decisions had kept competitors, page experience, Local and Analytics out of the App on purpose; they came in only as read-only evidence. The App became the place a person checks the AI’s work, not a second opinion competing with it.
Considered: a site health score, App-only queries that could drift from what MCP returns, keeping one screen per artifact type and adding more of them
-
04
An inconclusive check keeps the last good answer.
A mobile rank check for querywright pricing once reported the site as not found when it was there. Rather than patch that one result, I read all 95 retained rank observations to find the pattern and wrote the rule down: an inconclusive result is its own read state, decided by the structure of the response and never by its text. The current position stays empty after it, the last reliable position is kept beside it, and the stored rows are never rewritten.
Considered: reporting the page as dropped, rewriting the stored observation, matching on the provider’s result text
Open for sign-up, and still not overstating it.
The authenticated proof on the September release was ACMeridian’s own site: 46 observed pages in one research snapshot and fifteen distinct approvals, each with its own copy and verification lineage. One verification came back ready with 23 checks passing. Another came back not ready, with 28 passing, two needing a human, and four not verifiable, and the browser showed exactly that instead of rounding it up to a score.
Since then the product has opened its doors. Sign-up has been live since September 20, with a Founding Beta for the first ten paying customers, and Querywright runs its own site’s SEO through itself, from the approved plan to the checks after publishing. The codebase is about 85,000 lines of TypeScript across the App and the MCP Worker. On the October 15 security release, 2,575 tests passed across 363 files against Postgres, 502 in the MCP Worker and 137 in the browser suite.